
I’m not going to ask you to imagine a scene. I’m going to tell you about one that happened to me.
I was on a project, minding my own business, when a regulatory audit landed. The kind that doesn’t give you a heads-up. The kind that needs the data yesterday.
We went to the central data team. The answer: “Three months.”
Three. Months. For an audit that needed data now.
By escalating the problem (a meeting with leadership, reprioritizing, moving heaven and earth) we managed to shorten the timeline. But at what cost? By bumping other requests out of the queue that, okay, maybe weren’t as urgent, but were still necessary for whoever had asked for them. The Marketing guy who’d been waiting six weeks for his dashboard. The controller who needed to close out her quarterly report. All pushed aside.
And here’s the part nobody talks about: when teams see that the central queue is a black hole where requests go in and never come out, what do they do? Exactly. They build their own. Their own Excel files, their own extracts, their own mini-databases with no governance whatsoever. Duplicates everywhere. Unmanaged zones. Data nobody audits.
And the worst part: every one of those workarounds is born as “something temporary.” A tactical plan to get by. “We’ll migrate it to the official system once there’s capacity.” But that capacity never comes. And the temporary becomes permanent. Layer upon layer, patch upon patch, until one day you look at your data ecosystem and what you have is what software engineering calls a Big Ball of Mud: a giant ball of mud where everything is connected to everything, nobody knows exactly what depends on what, and touching any piece is terrifying because you don’t know what’s going to break.
The cure ends up worse than the disease.
And meanwhile, the question is still hanging there: if today we have cloud databases that crunch petabytes in seconds, if Spark does in minutes what used to take hours, if we have dbt, Airflow, Databricks, Snowflake and a thousand other tools…
Why are data teams slower than we were in 2005?
The problem isn’t technology. The problem is that “data-centric” companies have run headfirst into an organizational wall. We call it The Centralist Paradox.
Understanding the Centralist Paradox
For years, the best-practices playbook said: “Create a single central Data Engineering team. They ingest, clean and serve data to the whole company.”
That worked when you had three reports and an Oracle database. But today, with 15 lines of business asking for real-time dashboards, ML models that need fresh features every week, and a regulator asking you to prove the lineage of every number you publish… it doesn’t work anymore.
What you have is an unsustainable paradox with two crystal-clear symptoms.
Symptom 1: The Bottleneck (IT does everything, but it doesn’t scale)
A central team of 8–12 data engineers trying to serve Marketing, Risk, Finance, Operations, Compliance, Actuarial and Product. At the same time. With the same people.
It is mathematically impossible for a single team to grow at the pace of an entire organization’s analytical needs. If last year you had 40 requests a month and this year you have 120, you’d need to triple the team. But HR approves one hire. Maybe two, if you’re lucky.
The result: a request queue that grows faster than your capacity to deliver. Time-to-Value balloons from days to months. And when the queue becomes a black hole, business teams do the only thing they can: build their own solutions. Excel with macros. Manual extracts. Mini-databases in Access or Google Sheets. Nobody can blame them: they have a business to run.
But the collateral damage is brutal: duplicates everywhere, data with no lineage, entire zones with no management or governance. Every tactical fix that ends up as “the final version” adds one more layer to the ball of mud. And when an audit comes (and it always comes), you don’t just have to answer with data: you have to find it first, scattered across an archipelago of silos nobody documents.
If this sounds familiar, you’re not alone. A Monte Carlo Data study estimated that data teams spend 40% of their time on reactive work: putting out fires, answering ad-hoc requests and fixing broken pipelines. Only 26% of their time goes into building new things.
Symptom 2: Business Blindness
Your data engineers are rock stars at Spark, Airflow or dbt. They know how to tune a pipeline until it flies. They know how to partition tables, manage schemas and deploy on Kubernetes.
But they don’t know what the data means.
This isn’t their fault. It’s a consequence of the centralized model. A generalist data engineer has no reason to know the difference between a “Net Premium” and a “Gross Premium.” Or what a “Weighted Average Balance at Amortized Cost” means. Or when a “Customer” stops being a “Customer” and becomes a “Former Customer” under IFRS 17.
On the other hand, the Risk actuary, the Marketing analyst or the Finance controller know these concepts inside out. They live with them every day. But they don’t know how (and shouldn’t have to) build a pipeline in Spark.
The result is an infinite loop of iterations:
- The business writes a requirement (usually ambiguous, in a Word doc).
- Engineering interprets it (usually wrong, because it lacks context).
- A pipeline gets built.
- The business reviews it: “No, this isn’t what I asked for. The exchange-rate adjustment is missing.”
- Back to step 2.
- Repeat 4–7 times.
Each iteration takes days. Multiply that by 120 requests. The result: mutual distrust, frustration and slow decisions.
“Those who know can’t. Those who can don’t know.”
The Trap: “Well, let’s do Data Mesh!”
At this point, someone in a meeting room (usually someone who just finished Zhamak Dehghani’s book) raises a hand and says the magic word: “Let’s decentralize. Let every department own its data.”
It sounds great in theory. It resolves the paradox in one stroke: whoever knows Risk builds the Risk data product. Whoever knows Marketing builds the Marketing one. Every domain is autonomous. The business people, who know what things mean, work shoulder to shoulder with the engineers on their own team.
But when companies try to put this into practice, they run into an enemy even worse than the bottleneck: the anarchy of silos.
The kitchen metaphor: why silos are a disaster
To understand why this fails, let’s think about a professional restaurant.
In a serious kitchen, work is organized into specialized stations. There’s a sauce domain (the saucier), a pasta domain, a meat domain, a pastry domain. Each station is an expert in its own thing. The saucier makes the best sauces in the world. The pasta cook makes tagliatelle that will change your life. The meat cook nails the doneness every single time.
This is exactly what Data Mesh proposes: each domain specializes in its own data product. Risk is the expert in risk data. Marketing in campaign data. Finance in accounting data. Each one is autonomous, each one knows its subject matter deeply.
So far, so good. Autonomy works. Each station produces a flawless product within its specialty.
But now comes the moment of truth.
The maître d’ (the CEO, the regulator, the CFO) walks into the kitchen and orders a complex dish. He doesn’t want a bowl of plain tagliatelle. He doesn’t want sauce in a saucepan. He wants a composed dish: tagliatelle with Bolognese sauce, grated Parmesan and a side of sautéed vegetables.
In other words: he needs the output of SEVERAL stations to come together into a single, coherent dish.
In data, this “composed dish” has very specific names: a Risk Data Aggregation (RDA) report. An accounting close. A Solvency II regulatory report. A 360-degree customer view. Any deliverable that crosses domains.
And this is where it all falls apart.
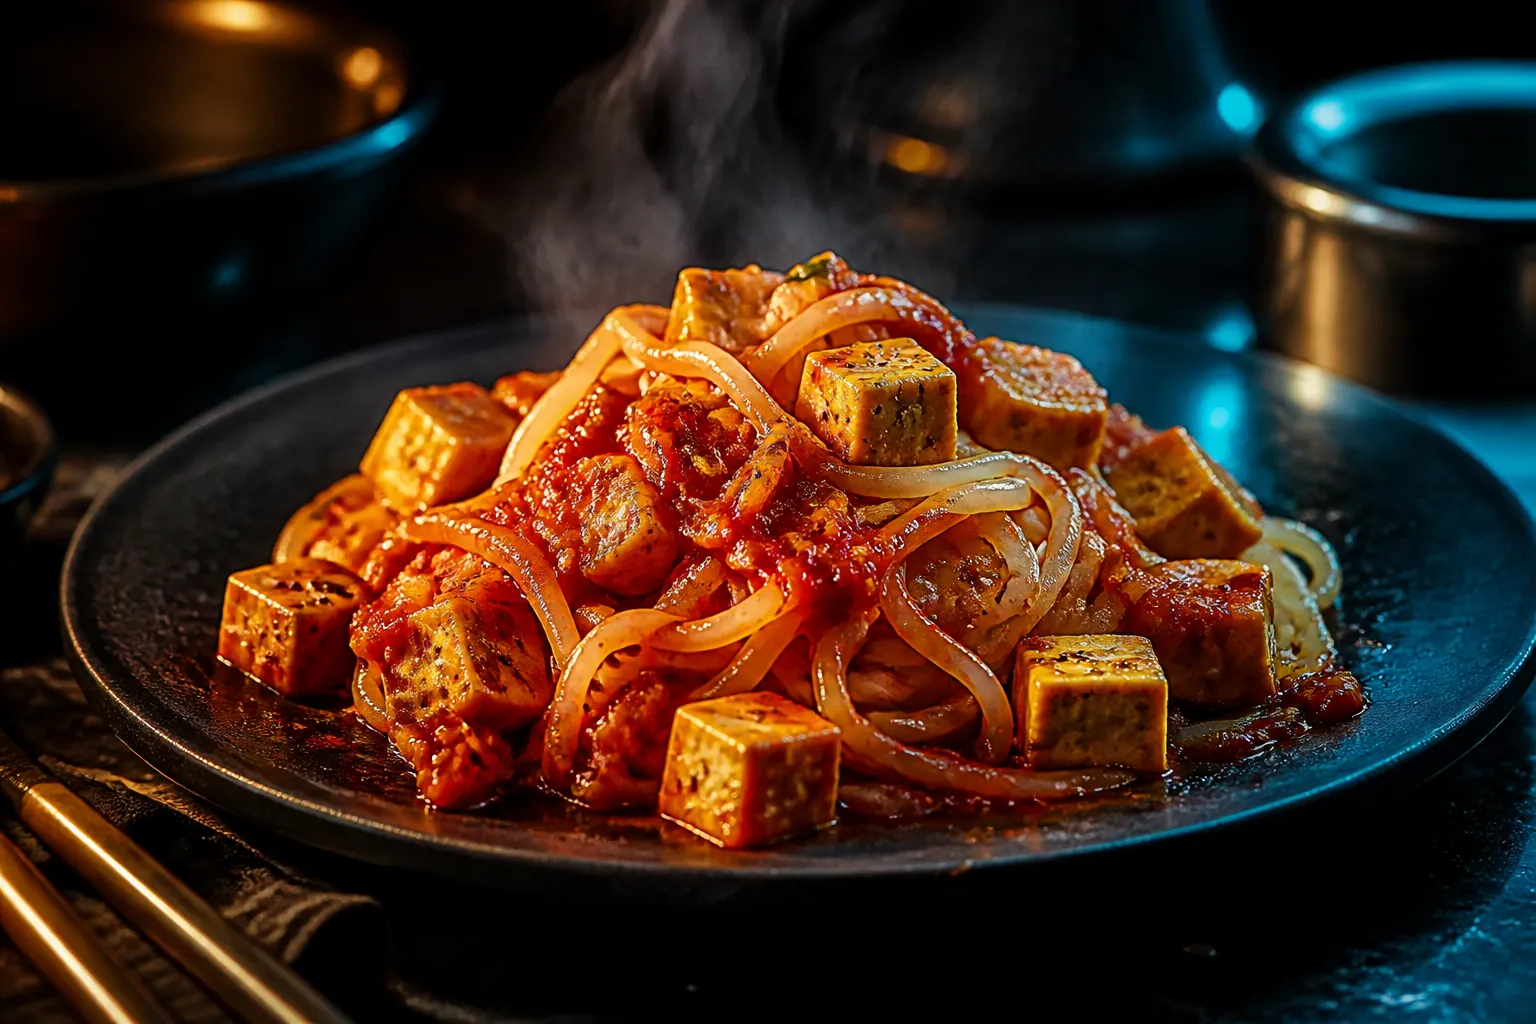
Because each station has optimized for its own world. The pasta cook has made Asian rice noodles (perfect in their context). The saucier has made a Neapolitan pizza sauce (perfect in his). And the cheese station has prepared marinated tofu (because in their domain, that counts as “cheese”).
Now try to put that dish together. You’ve got rice noodles with pizza sauce and marinated tofu. Every ingredient is excellent on its own. Together, they’re a culinary Frankenstein.
Let’s bring this over to an insurance company’s data:
- The Marketing domain manages campaigns, leads and interactions. For them, a “Customer” is anyone who has interacted with a campaign, whether they bought or not. Their table has 23,000 records.
- The Risk domain manages policies, claims and scoring. For them, a “Customer” is the holder of an active policy. Their table has 8,500 records.
- The Sales domain manages the sales pipeline. For them, a “Customer” is a lead with activity in the last 90 days. Their table has 12,000 records.
All three are brilliant specialists. All three are right within their domain. But no domain bothered to make sure its definition of “Customer” was compatible with the neighbor’s.
Now the CFO walks in and asks for the RDA. This report needs to cross customers from all three domains with their policies, their financial positions and their sales activity. It’s the “composed dish.”
What customer count do we report? Marketing says 23,000. Risk says 8,500. Sales says 12,000. The amounts don’t reconcile. The keys don’t join. The time periods don’t line up.
Rice noodles with pizza sauce.
It’s not a technology problem. It doesn’t matter whether you use Snowflake, Databricks or a Hadoop cluster held together with duct tape. If each domain has defined “Customer” optimizing for its own context without thinking about the final plating, the cross-domain dish will always be a disaster.
Congratulations! You’ve swapped a centralized bottleneck for an archipelago of disconnected fiefdoms. Each island produces flawless data within its borders, but none of it can be combined with anyone else’s.
The real challenge: you need a common language (without re-centralizing)
Back to the kitchen. How does a professional restaurant solve this problem?
Not by re-centralizing (that would mean the executive chef cooks everything alone, and we’ve already seen that doesn’t scale). What it does is establish agreements between stations.
The saucier is still the sauce specialist. But the executive chef has defined a contract: “If a sauce is going to accompany Italian pasta, it must have a San Marzano tomato base, texture X and seasoning level Y.” The saucier keeps the freedom to create variations, but honors the contract whenever his sauce is going to be combined with another station’s products.
In other words: each station still owns its product, but there’s an agreement on how the pieces “plug in” when a cross-station dish has to be assembled.
In software engineering, this concept has a name: it’s called a Shared Kernel, a Domain-Driven Design pattern. It’s not a centralized database. It’s not a central team that controls everything. It’s a minimal agreement on the identity of the concepts that cross domains: what exactly a Customer is, what a Contract is, what a Product is.
In our insurance company, the Shared Kernel would define:
“A Customer is a natural or legal person with a valid tax ID (NIF) who has had at least one contractual interaction with the company.”
That’s the shared identity. It’s the “standard plug” everyone respects. It doesn’t say how Marketing should use that Customer, or which fields Risk needs. That’s still each domain’s business.
But when Marketing talks about a “Customer” with NIF 12345678A, Risk knows exactly which Customer that is. And when the CFO asks for the RDA, the domains can cross their data because they all start from the same base identity.
Then each domain adds its own layer of specialized context:
- Marketing adds: campaign history, contact channels, engagement scoring.
- Risk adds: active policies, loss ratio, risk level.
- Sales adds: pipeline stage, recent activity, close probability.
Each station keeps cooking its own thing. But now, when the maître d’ orders the composed dish, the tagliatelle is Italian, the sauce is Bolognese and the cheese is Parmesan. Everything fits.
The key: data governance has to be software, not a PDF
This is where 90% of companies get it wrong.
They think data governance is a bureaucratic committee that approves documents. A group of 12 people who meet every two weeks to validate field definitions in an Excel file and produce a “Business Glossary” PDF that gets uploaded to the intranet and that nobody ever reads again.
Glossary 2.0, on page 47 of the governance manual, says “Customer” is defined as… wait, which version is current? The January PDF or the March Word doc? Did anyone update the pipelines when the definition changed?
Of course not.
The problem is fundamental: the documentation (what the data MEANS) lives separately from the code (what the data DOES). They’re two parallel worlds that fall out of sync on day one and drift a little further apart with every sprint.
The most important thing about data is quality. And quality isn’t a filter you apply at the end to see how many errors slipped through: it’s an engineering contract guaranteed in the production recipe itself. If data isn’t born governed, clean and versioned from its very first extraction, it isn’t a corporate asset: it’s a ticking time bomb in your warehouse.
What “Operable Governance” means in practice
Think about how modern software development works.
No serious team writes its API documentation in a PDF separate from the code. They use OpenAPI (Swagger): a YAML file that lives in the same repository as the code. If you add a new endpoint, you define it in the YAML and the tooling automatically generates the documentation, the tests and even the client stubs. If you change the YAML, the code is forced to change too.
The documentation can’t fall out of sync with the code. They’re the same thing.
So why do we keep doing the opposite with data?
Imagine that the definition of what a “Customer” is doesn’t live in a PDF on SharePoint. It lives in an executable catalog: a structured file (YAML, JSON, whatever you like) that describes:
- Identity: which fields uniquely define a Customer (NIF, person type).
- Quality rules: the NIF can’t be null, it must have a valid format, the sign-up date must be before today.
- Relationships: a Customer can have N Contracts. A Contract belongs to exactly 1 Customer.
- Versioning: when the definition last changed, who approved it, what the previous version was.
And now, the magic: when you “run” that definition, an engine reads it and automatically generates:
- The base tables in your data warehouse (with the exact structure the definition dictates).
- The quality checks (which run before every load).
- Up-to-date documentation (which is the catalog itself, not a separate PDF).
- The data contracts for downstream consumers.
Three things change radically when you do this:
- Documentation and code can’t fall out of sync. They’re the same thing. No more “well, the PDF said something else.” If you change the definition, the pipeline is regenerated with it.
- Governance stops being a “cop” that slows development down and becomes the “engine” that speeds it up. Adding a new column doesn’t mean touching five pipelines by hand: you update the recipe and the engine regenerates everything that’s needed.
- And the most important one: business users can generate their own data products. Without depending on another department. Without waiting three months in a queue.
This is what truly changes the game. It’s not just that “it takes less time.” It’s that the dependency disappears.
To put numbers on it: on projects I’ve worked on, manually modeling a single source table in Data Vault 2.0 (analysis + design + DDLs + DMLs + tests + documentation) took between 16 and 32 hours of work. Multiply that by 100, 200 or 2,000 sources and you’re looking at person-years just for the base layer. When you automate generation from an executable catalog, that time drops to 1–2 hours per table. 93% less. And more importantly: those 1–2 hours can be done by the business analyst, not a specialized data engineer.
The base layer of a methodology like Data Vault is simple and standardized enough to be automated robustly. When you do that, what used to be a bottleneck (the central team hand-cranking SQL) becomes a tool the business itself can use. The actuary, the controller, the risk analyst can create their own data products, with the guarantee that what they generate is auditable, consistent with the rest of the ecosystem, and scalable.
Without breaking anything. Without duplicates. Without ungoverned zones. Without adding another layer to the ball of mud.
Remember the audit I told you about at the beginning? The one with the three-month wait. With this model, the Compliance team wouldn’t have needed to ask anyone for anything. They’d have defined their data product, the engine would have generated it, and the data would have been available by the next load. Without bumping the Marketing guy out of the queue. Without anyone building a parallel Excel file out of desperation.
That’s the real shift: it’s not doing the same thing faster. It’s every team being able to do it themselves, in a governed way.
Why this matters NOW
Maybe you’re thinking: “Okay, sounds good, but my company already has something that more or less works.”
The problem is that “more or less” has an expiration date. Three forces are squeezing data teams like never before:
- Force 1: Regulatory pressure. DORA, IFRS 17, BCBS 239, the EU AI Act… All of these regulations have something in common: they require you to prove the lineage of every data point, from the source to the final report. When an audit lands, it doesn’t give you three months: it gives you three days.
- Force 2: The speed of the market. Your competitors are shipping data products (ML models, real-time dashboards, automations) in weeks. If it takes your team weeks to model a single source table, you’re surviving instead of competing.
- Force 3: The cost of technical debt. Every artisanal pipeline you write by hand is debt that accrues interest. Those “temporary” Excel files that have been in production for three years, those manual extracts and those patches are what make up the Big Ball of Mud.
The combination of these three forces makes the artisanal model of hand-cranking SQL unsustainable. You don’t need more engineers or a bigger central team. You need every team to be able to create its own data products autonomously, with governance, and with quality built in.
And so this doesn’t sound like theory: I’ve specified platforms for environments with more than 2,000 data sources and more than 50,000 managed artifacts (DDLs, DMLs, quality tests, transformations). At that scale, craftsmanship isn’t an option. Either you industrialize or you don’t make it.
From theory to the kitchen (literally)
This article opens The Artificer — the data kitchen: fifteen essays on how to put this into practice, step by step, no smoke and mirrors:
- How to build the Shared Kernel using Data Vault 2.0 patterns.
- How to apply Domain-Driven Design to data so the architecture mirrors the business.
- How to go from craftsmanship to an automated Data Factory.
- How to get teams working in parallel without stepping on each other’s toes and without breaking global consistency.
From here on, we’re stepping into the kitchen. Literally.
We’re going to use the full metaphor of a professional restaurant to understand every layer of a modern data architecture: from the raw ingredients (the raw data from the source system), through the mise en place, all the way to the final plating.
And we’ll see that, just like in a professional kitchen, the key isn’t having better pans. It’s having better recipes.